The Modern Sound of Storytelling: Exploring ElevenLabs and the New Horizon of AI Audio Creation
In an era dominated by rapid visual consumption, voice remains our most intimate medium. A subtle inflection, a well-timed pause, or a shift in warmth can transform sterile words into an emotional journey. For decades, achieving studio-grade voice work required extensive recording environments, specialized audio hardware, and lengthy post-production cycles. Today, that barrier is dissolving. As our selected AURAZYRA PICK in AI & Creativity, ElevenLabs stands at the forefront of this shift, offering an advanced AI voice and audio creation platform engineered for pristine, natural-sounding results.
Whether you are producing long-form narration, generating localized audio for international audiences, or prototyping character voices for creative media, ElevenLabs redefines how creators translate written concepts into high-fidelity sound. In this editorial guide, we delve into the capabilities, workflows, and creative strategies that make this platform an essential instrument in the modern digital studio.
The Architecture of Natural-Sounding AI Voice
Early iterations of synthetic speech were notorious for their robotic cadence and monotone delivery. While they served functional utility in automated alerts and basic screen readers, they lacked the nuanced prosody of human speech. ElevenLabs fundamentally bridges this gap by applying deep generative modeling to the cadence, rhythm, and tonal subtleties of human vocalization.
The core philosophy of the platform revolves around contextual awareness. Rather than reading words in isolation, modern speech synthesis models analyze surrounding syntax and emotional resonance. The result is speech that breathes, accelerates with urgency, or softens with reflective pauses. For writers, directors, and multimedia producers, this means the finished audio resonates with authentic narrative gravity rather than mechanical precision.
Core Capabilities: From Script to Studio-Quality Audio
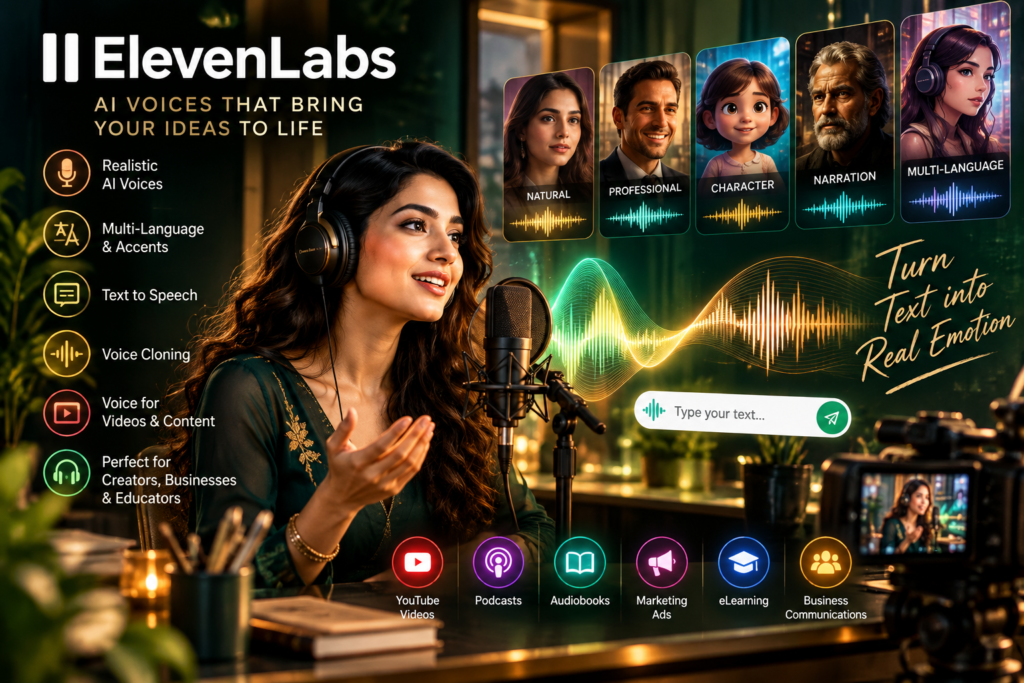
ElevenLabs is designed as an end-to-end environment for vocal synthesis and audio composition. Understanding its primary tools allows creators to match the right capability to their specific production demands.
1. Expressive Text-to-Speech (TTS)
At the center of the platform is an intuitive text-to-speech engine capable of generating rich spoken audio from pure text input. Creators can paste scripts, draft notes, or complete chapters and immediately hear them vocalized across a diverse spectrum of tonal profiles. From grounded, authoritative narrators to lively commercial reads, the breadth of stylistic choice allows for rapid auditory experimentation.
2. Voice Creation and Customization
One of the platform’s standout dimensions is voice creation. Instead of relying on a handful of static, overused voice presets, creators can sculpt unique vocal identities tailored to specific characters, branded experiences, or editorial formats. This capability empowers creative directors to maintain a distinctive sonic signature across entire product lines, YouTube channels, or narrative podcasts.
3. Multilingual Audio and Global Reach
Expanding content internationally has traditionally been one of the most resource-intensive aspects of production. ElevenLabs incorporates robust multilingual audio capabilities, allowing creators to bridge cultural and linguistic divides. By generating fluent, natural voice output across multiple languages, teams can distribute audiobooks, corporate communications, and instructional materials globally without sacrificing expressive clarity.
4. Long-Form Narration and Content Production
Short voice bites are useful for social snippets, but sustained narration requires rigorous consistency. ElevenLabs supports comprehensive content production workflows, ensuring that chapters, extensive articles, and serialized audio dramas maintain uniform volume, tone, and pacing from the opening line to the final sign-off.
Strategic Use Cases for Contemporary Creators
Integrating synthetic audio into creative pipelines requires deliberate artistic direction. Below are several ways forward-thinking teams are utilizing ElevenLabs to amplify their creative bandwidth.
- Independent Audio Publishing: Authors and self-publishers can convert manuscript backlists into immersive audiobooks, offering readers a rich auditory experience without prohibitive studio overhead.
- Video and Documentary Production: Video creators and documentary filmmakers can generate voiceover temp tracks during editing, refine scripts organically against visuals, and finalize polished voice tracks on demand.
- Educational and E-Learning Systems: Educational developers can produce warm, engaging instructional guides in multiple languages, making complex curricula accessible to diverse global learners.
- Game Development and Prototyping: Independent game studios can voice expansive dialogue trees for non-player characters during the prototype stage, bringing virtual worlds to life long before final casting begins.
- Inclusive Accessibility: Digital publications can seamlessly introduce audio editions of long-form journalism, offering alternate consumption avenues for neurodivergent listeners or users on the move.
Editorial Guidance: Crafting Effective Spoken Scripts
Generating pristine audio requires more than high-grade software; it demands intentional writing. When writing for voice synthesis, remember that words read silently in a notebook interact differently with an auditory audience than those delivered out loud.
- Punctuate for Breath: Generative models interpret commas, em dashes, and ellipses as dynamic pacing cues. Use thoughtful punctuation to guide where the voice should pause, deliberate, or pivot.
- Read Scripts Out Loud: Before pasting extensive copy into the platform, recite your text verbally. If a phrase feels tongue-twisting to a human speaker, simplify the syntax to achieve natural vocal rhythm.
- Test Vocal Personas Early: Select a voice persona that matches the emotional premise of your content. A solemn historical recap demands a grounded, measured delivery, whereas a fast-paced creative tutorial thrives on dynamic brightness.
Frequently Asked Questions
What makes ElevenLabs different from conventional text-to-speech tools?
Traditional text-to-speech tools often produce rigid, robotic speech with flat cadence. ElevenLabs focuses on realistic acoustic nuances, generating natural intonation, dynamic pacing, and contextual awareness that sounds conversational and human.
Can ElevenLabs handle multiple languages?
Yes. The platform provides multilingual audio generation, enabling creators to produce realistic vocal performances across numerous global languages for localized content distribution.
Can I design my own unique voice styles?
Yes. ElevenLabs includes dedicated voice creation tools, allowing users to craft custom vocal identities tailored for distinct characters, branding efforts, and narrative projects.
What types of projects benefit most from this platform?
The platform excels across diverse media, including audiobooks, video voiceovers, documentary narration, gaming prototypes, educational e-learning modules, and accessibility-focused audio reading.
The AURAZYRA Verdict: A Milestone in Sound Design
The spoken word is a timeless medium of human connection. By blending natural cadence, voice design freedom, and multilingual versatility, ElevenLabs opens new creative avenues for storytellers and media innovators. If your creative journey involves sound, narration, or bringing written narratives into the auditory realm, exploring ElevenLabs will fundamentally enrich the way you create.